Beyond LLMs: What TypeSafe Jev Means for System One AI
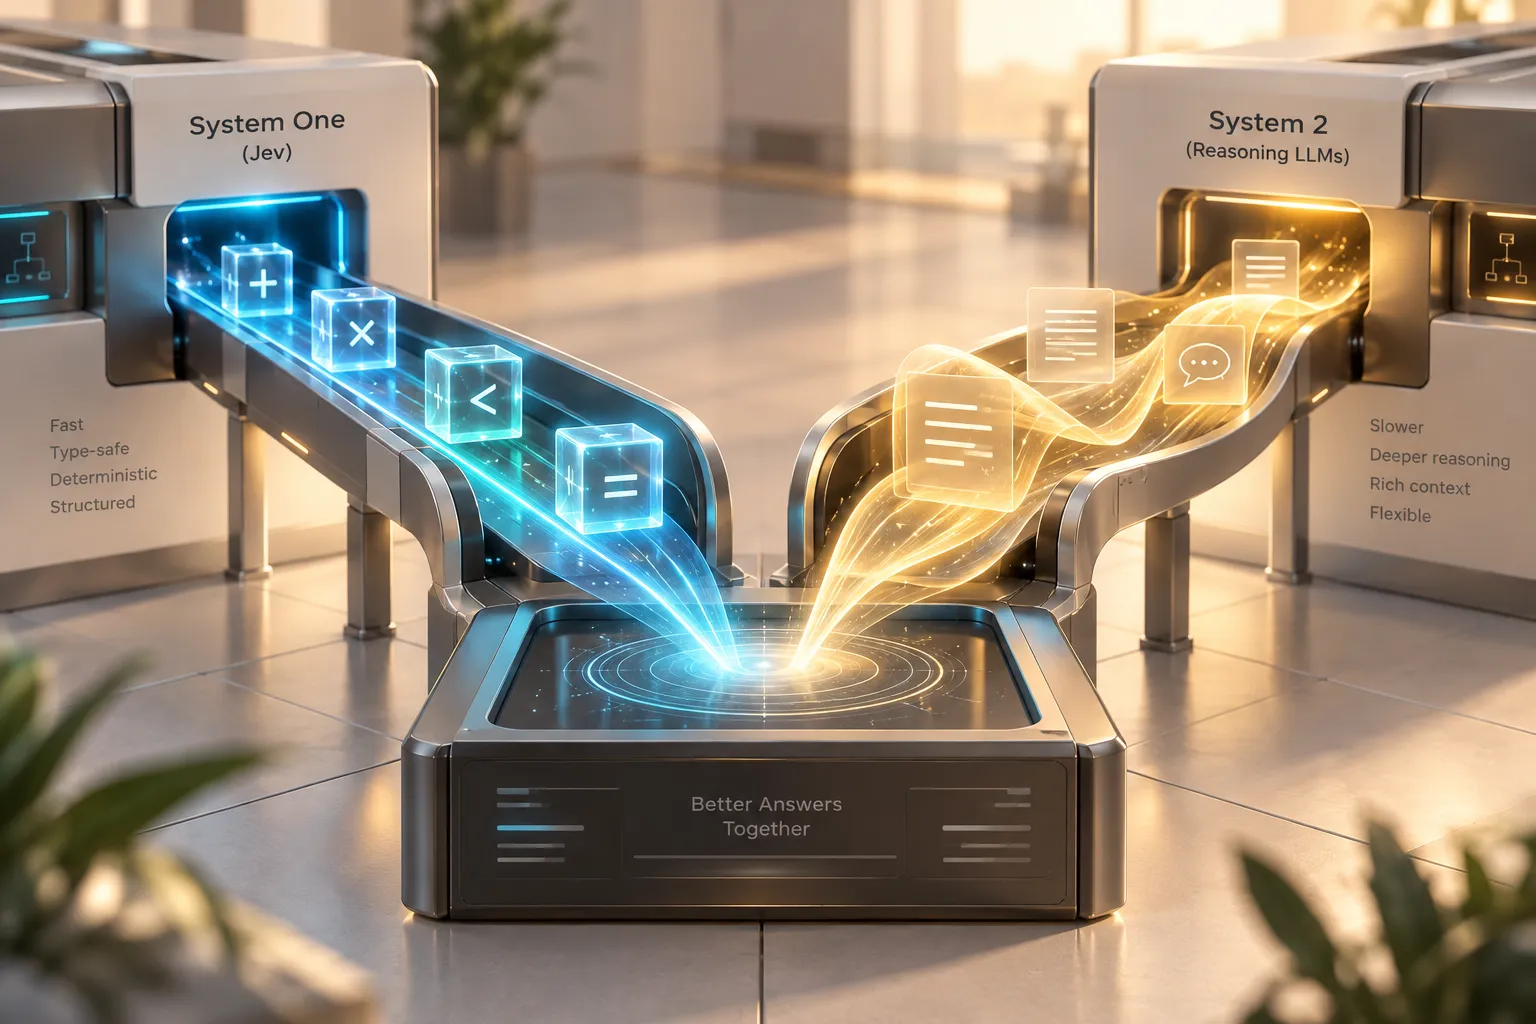
In behavioral economics, Nobel laureate Daniel Kahneman introduced the world to System 1 (fast, instinctual, parallel decisions) and System 2 (slow, deliberate, analytical reasoning).
For years, the generative AI boom has been obsessed with building massive System 2 engines: giant reasoning LLMs like Claude 3.5, GPT-4, and Gemini 1.5 that write essays, compose code, and solve complex multi-step problems.
However, software development faces a silent bottleneck: most operations inside modern apps don't require complex reasoning or natural language prose. They require ultra-fast, structured decisions—like routing a ticket, assigning a confidence score, or detecting spam. Using a giant chat LLM for these tasks is like hiring a philosopher to flip a light switch: it’s slow, expensive, and prone to breaking JSON parsers.
Enter Jev, the flagship System One Model released by TypeSafe AI.
If you build software with AI, here is a complete breakdown of what System One models are, how Jev works, and why this shift could fundamentally re-architect how AI fits into your production stack.
What is a System One Model?
A System One Model is an AI model engineered specifically for high-speed, bounded, and typed decision-making rather than open-ended text generation.
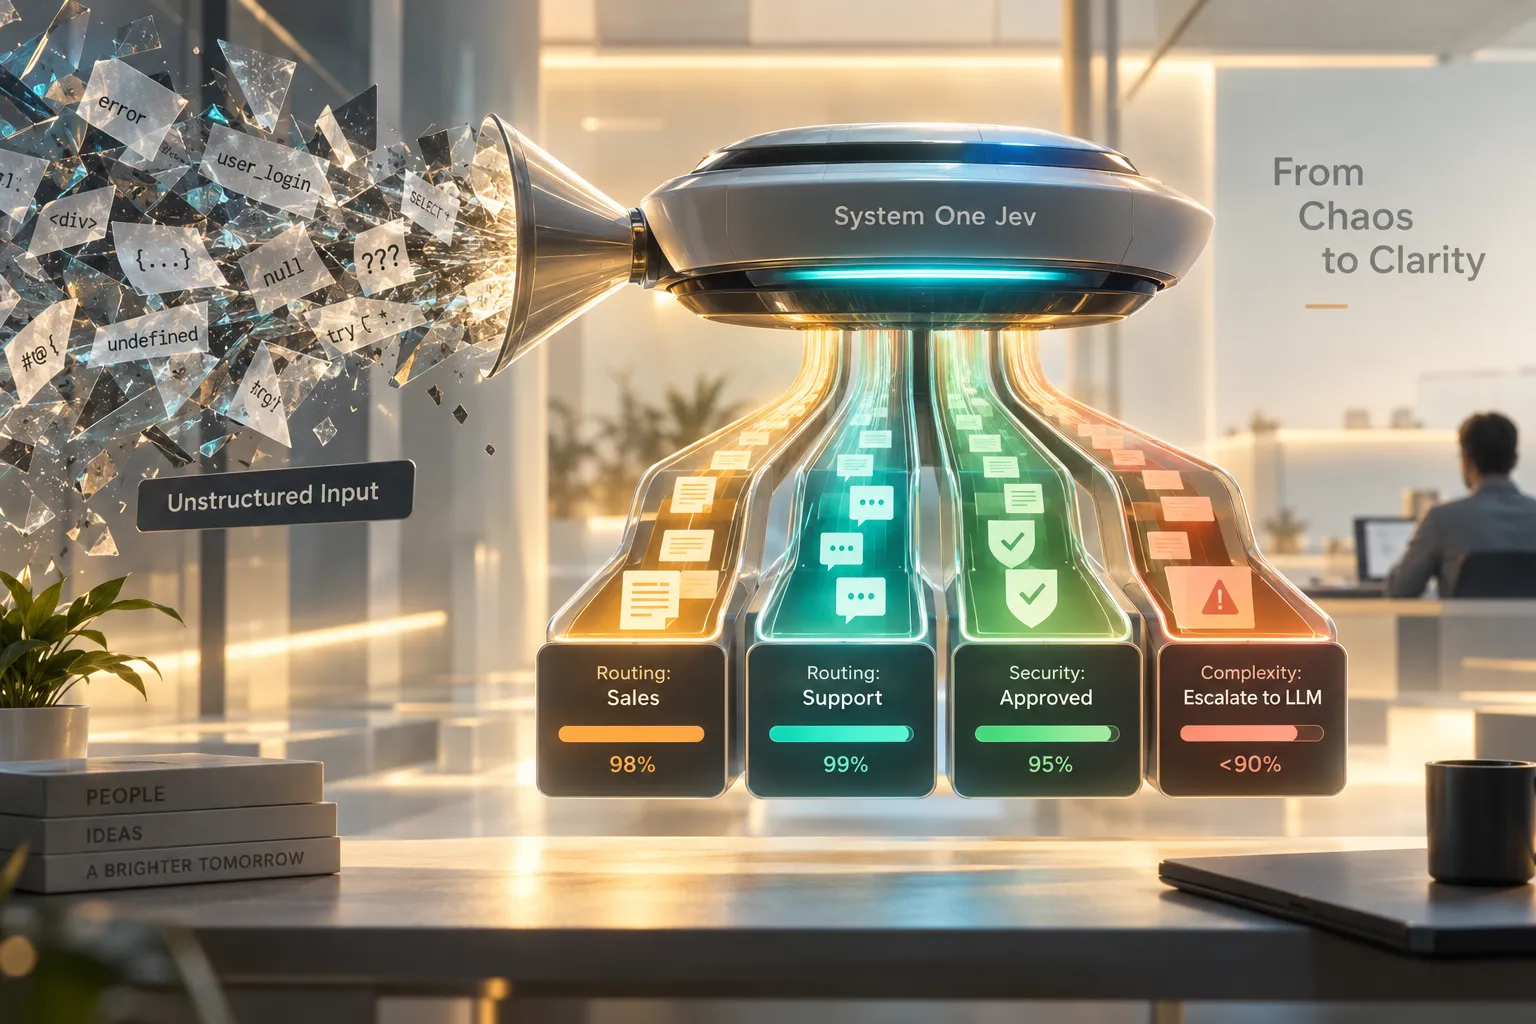
Instead of generating raw text token-by-token, a System One model accepts unstructured program state (e.g., text logs, user input, or JSON objects) and evaluates defined choices in a single parallel pass.
[Unstructured Input / State] ---> [ System One Model (Jev) ] ---> [ Type-Safe Decision + Probability ]
Rather than outputting prose, it returns type-safe primitives like:
- Choice: Categorical selection from a defined set of options (up to 255 options).
- Score: Numerical ratings along defined metrics.
- Boolean (Noul): Calibrated yes/no probabilities.
What Makes TypeSafe Jev Different from Standard LLMs?
To understand why developer adoption of Jev has surged, consider how it compares to standard frontier LLMs like GPT-4o or Claude:
| Feature | Standard Chat/Reasoning LLMs | System One Models (Jev) |
| Output Type | Unstructured Strings (Prose, JSON text) | Strictly Typed Values (Choice, Score, Boolean) |
| Sampling Mechanism | Auto-regressive (token-by-token) | Single parallel pass |
| Latency | 1 to 10+ seconds | 70ms – 500ms |
| Confidence Scoring | Often overconfident or uncalibrated | Calibrated probabilities per output |
| Type Errors / Schema Breakage | Risk of malformed output/JSON parsing failures | 0% type-error rate (by construction) |
| Primary Use Case | Content generation, chatting, agent reasoning | Ticket routing, spam detection, agent gating |
Key Advantages of the Jev System One Architecture
1. Zero Hallucinations and Type Errors
Because System One models do not generate free-form sentences, they eliminate formatting errors. Software applications do not need complex retry logic or defensive JSON parsing—the output strictly follows the schema declared in code.
2. Built-in Calibrated Confidence
Traditional LLMs notorious for confidently giving wrong answers. Jev is trained using techniques like Reinforcement Learning for Calibrated Decisions (RLCD), providing a mathematical probability alongside every decision.
This allows developers to build clean logic gates:
- Confidence > 95%: Execute automatically.
- Confidence < 80%: Route to human review or escalate to a heavier System 2 model (like Claude or GPT-4).
3. Latency and Cost Efficiency
By shedding the overhead of auto-regressive text generation, System One models run up to 40x–100x faster than traditional chat LLMs. Input token costs drop drastically, while standard output generation overhead is completely removed.
Real-World Use Cases: Where System One Fits in Your Architecture
Jev and System One models are not meant to replace LLMs like ChatGPT or Claude—they are designed to sit in front of or alongside them as a fast, deterministic decision layer.
                     ┌────────────────────────┐
                     │ Incoming User Request  │
                     └───────────┬────────────┘
                                 │
                                 ▼
                     ┌────────────────────────┐
                     │  System One (Jev API)  │
                     └───────────┬────────────┘
                                 │
          ┌──────────────────────┴──────────────────────┐
          │ High Confidence (>90%)                      │ Low Confidence (<90%)
          ▼                                             ▼
┌──────────────────┐                           ┌──────────────────┐
│ Automated Route  │                           │ System 2 (LLM)   │
│ or Tool Execution│                           │ / Human Escalation│
└──────────────────┘                           └──────────────────┘
Key Applications:
- Support Ticket & Lead Routing: Instantly categorizing incoming tickets (e.g., {billing, technical, sales}) and scoring urgency without parsing messy text responses.
- AI Agent Tool Authorization: Deciding whether a tool call should be approved automatically based on safety rules, eliminating delays in autonomous loops.
- Cascading RAG Pipelines: Evaluating whether retrieved vector document context is relevant before sending it to a costly generative model.
- Moderation & Guardrails: Scanning incoming user requests or model outputs for policy violations in under 100ms.
Limitations: What Jev CANNOT Do
To build effectively with System One models, it's essential to understand their boundaries:
- No Free-Text Generation: Jev cannot draft emails, write code, summarize long documents into prose, or chat.
- No Internal World Knowledge: Jev relies entirely on the state passed to it; it cannot browse the web or perform complex internal knowledge retrieval on its own.
- Requires Pre-Defined Schema: You must know the exact bounded set of choices or scoring criteria before making the API call.
The Verdict: The Dual-Model Architecture is Here
The launch of TypeSafe’s Jev marks a key shift in AI engineering. The era of using one massive, expensive LLM for every step in an application is fading.
Instead, production-grade applications are moving toward a hybrid architecture:
- System One (Jev): Handles fast, high-volume classification, tool selection, routing, and filtering at low latency.
- System 2 (GPT/Claude/Gemini): Takes over for long-form generation, complex reasoning, and open-ended analysis.
By delegating micro-decisions to System One models, developers can build AI systems that are faster, drastically cheaper, and mathematically reliable.
While backend architectures are moving toward low-latency models like Jev to streamline data, front-end presentation and reporting shouldn't be a bottleneck either. Discover how Presentation Intelligence (PI) helps teams create, structure, and automate high-impact pitch decks and reports instantly.